
Guided tour
This page follows one piece of work from beginning to end: a job run over a file of molecules, and the result it produces. It is one journey rather than a description of every screen — the how-to guides describe each one in full, and are linked along the way.
The job is sa-score, which calculates a synthetic accessibility score for each molecule it is given. It is quick, and it is a good shape for a first run: one input file, one output file.
What you need before starting is an account you can sign in with, and a project to work in. The Logging in and Getting started guides cover both, and Concepts explains the words used below.
1. Open the project
Sign in from the Account menu, then choose Projects in the main navigation and select the project you want to work in. That opens the project's Files, and a strip appears below the masthead naming the project and offering its four sections — Files, Run, Results and Manage.
The project you are working in is always the one in the address bar, so the page, the data it shows and the link you can share always agree. See the Projects guide.
2. Put the data in the project
Everything that runs in a project has access to that project's files, so the input has to be there before it can be used. Upload it in Files, or attach an existing dataset version from Datasets.
This tour uses a file called clustered_props.sdf, an SD-file of 1000 molecules that is already in
the project. See the Files guide for uploading, and the
Datasets guide for attaching.
3. Find the job
Open the project's Run section. It is the catalogue of everything this deployment lets you
launch — workflows, applications and jobs — presented as cards, and the search field
narrows it. Typing sa-score leaves one card.
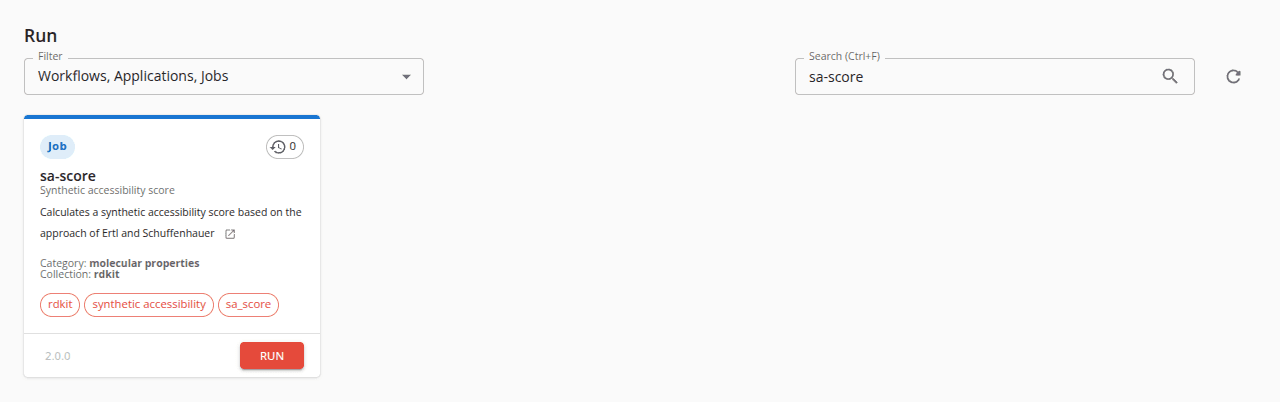
The card states what the definition is and what it does: the blue chip marks it as a Job, the heading is its identifier and the line beneath the fuller name it is published under, and its category, collection and keywords sit below the description. The chip on the right counts how many times this version has already run in this project. The footer holds the version being offered and the Run control.
The Run guide reads the card part by part.
4. Launch it
Choosing Run opens the launch dialog. It leads with the definition's fuller name — Synthetic accessibility score — and asks for two kinds of thing:
- Inputs are project files. Molecules is required here, marked with an asterisk, and
Select file picks
clustered_props.sdffrom the project. - Options are the parameters of the run. Output file name is required; the rest have defaults that suit an SD-file, and are left alone.
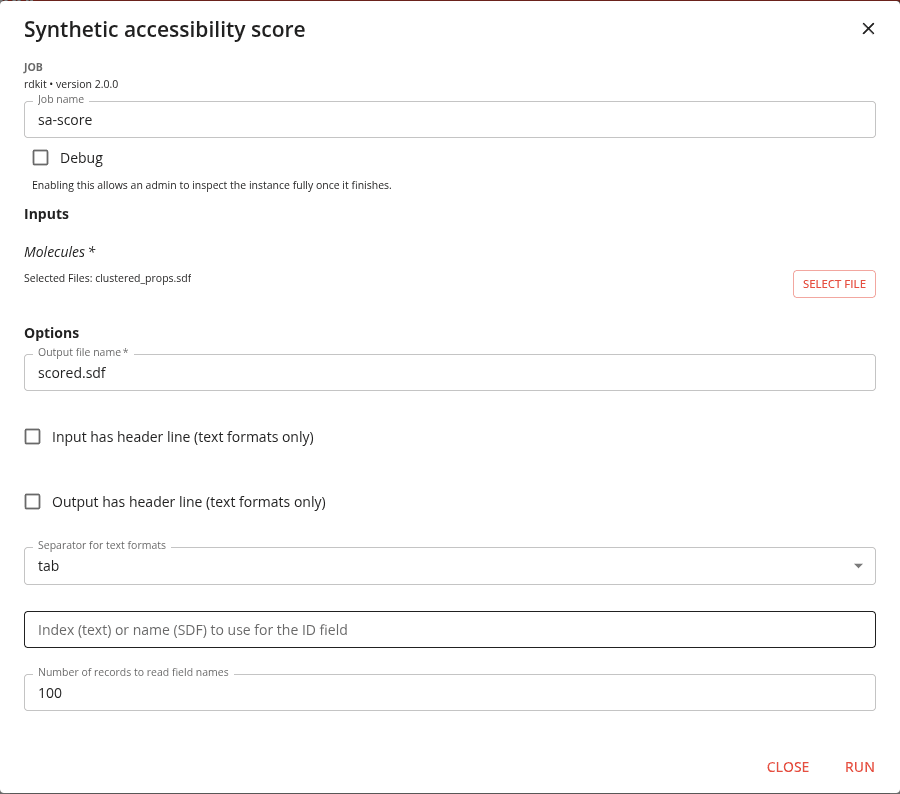
Run stays disabled until everything required has been given, so a launch cannot be sent
incomplete. Naming the output scored.sdf and choosing Run starts the work.
5. Follow it
A successful launch opens what it created under Results, so you land on the thing that was actually started rather than on a list you have to search.
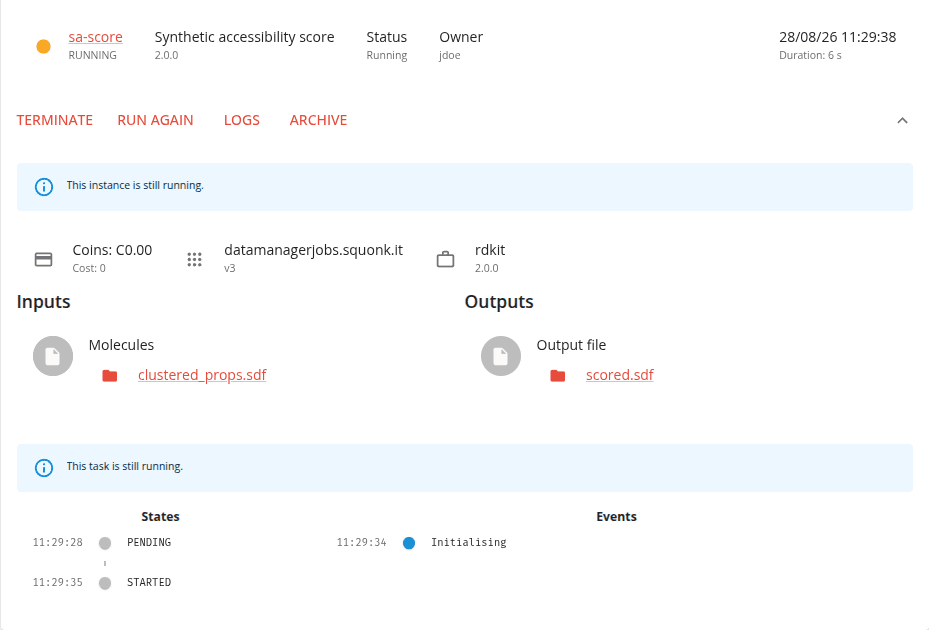
The result names the job, its status — RUNNING — its owner and how long it has been going. Under that are the controls for it: Terminate stops it, Run again reopens the dialog with these same choices, Logs opens that instance's own log directory in the project's Files, and Archive decides whether it is deleted automatically. Inputs and Outputs name the files it was given and the file it will produce, and States and Events report its progress as it goes.
The list does not refresh itself; Refresh results in the rail reads the section again.
6. Read the result
sa-score finished in 19 seconds.
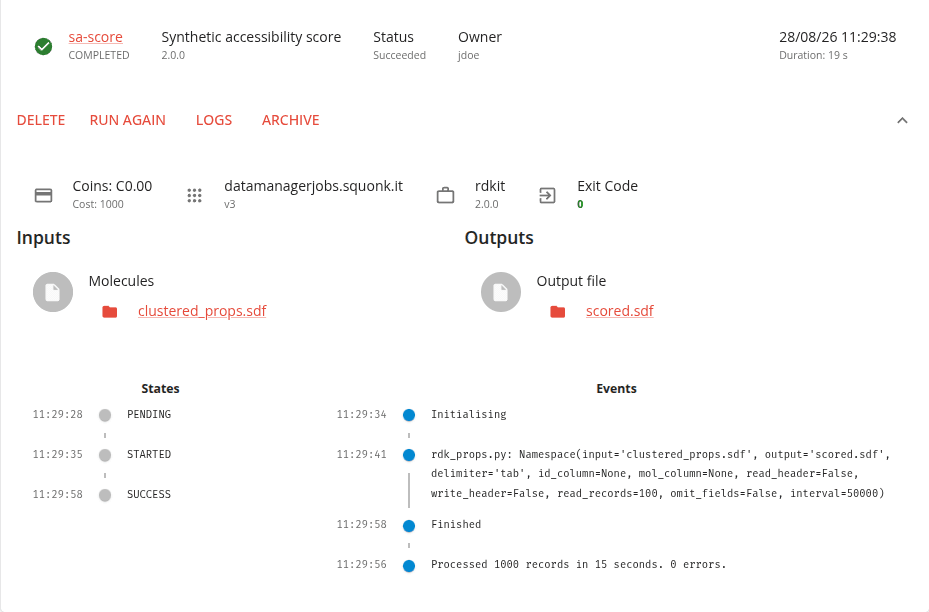
What changed when it completed:
- The status is COMPLETED and Succeeded, with an Exit Code of
0. - Coins and Cost are what the run reported spending —
C0.00and1000here. They are reported separately by the Data Manager as the work runs, and an instance that reported neither says nothing rather than naming a figure it never gave. - States ran
PENDING→STARTED→SUCCESS, and the Events record what the job actually did: the arguments it was called with, thenProcessed 1000 records in 15 seconds. 0 errors. - Terminate has become Delete, because there is no longer anything to stop.
The output file is a link, and it now sits in the project's Files alongside the input, ready to be the input to something else. A run that fails says so in the same place, with its events and logs to read; the Results guide covers reading one.
Remember to terminate a long-running application or job when you have finished with it, so it stops consuming resources.
Where this fits
That is one job over one file. The same three steps — put the data in the project, launch something from Run, read it under Results — are how everything else works too, including applications such as a Jupyter notebook, which stays running for as long as you need it, and workflows, which run a sequence of steps as one thing.
Two parts of the application sit outside a project:
- Datasets lists every dataset you can reach. A dataset is versioned and shareable, and a version can be attached to a project as an input.
- Administration holds the organisations, units and subscriptions behind your projects, with their charges and usage reports.
And within a project, Manage states its facts and holds the changes you can make: its coin usage, the people who can reach it, its privacy, and its deletion. It stays readable to everyone who can see the project, so you can always check a project's details even where you cannot change them.